
The open-science world has, after years of real effort, largely agreed on how to package research data. RO-Crate, Frictionless Data, BagIt: a dataset should carry a machine-readable manifest that says what it is, who made it, what license governs it, and where it came from. This is progress worth naming. A folder of loose CSVs with the meaning living in someone’s head, or worse, in a slide deck, is how data dies. A described package is findable, attributable, and reusable in a way a bare directory never is. If your consortium is deciding what to require, requiring a packaging standard is a good early answer.
But “self-describing” is quietly doing two different jobs, and only one of them is finished.
Two kinds of self-describing
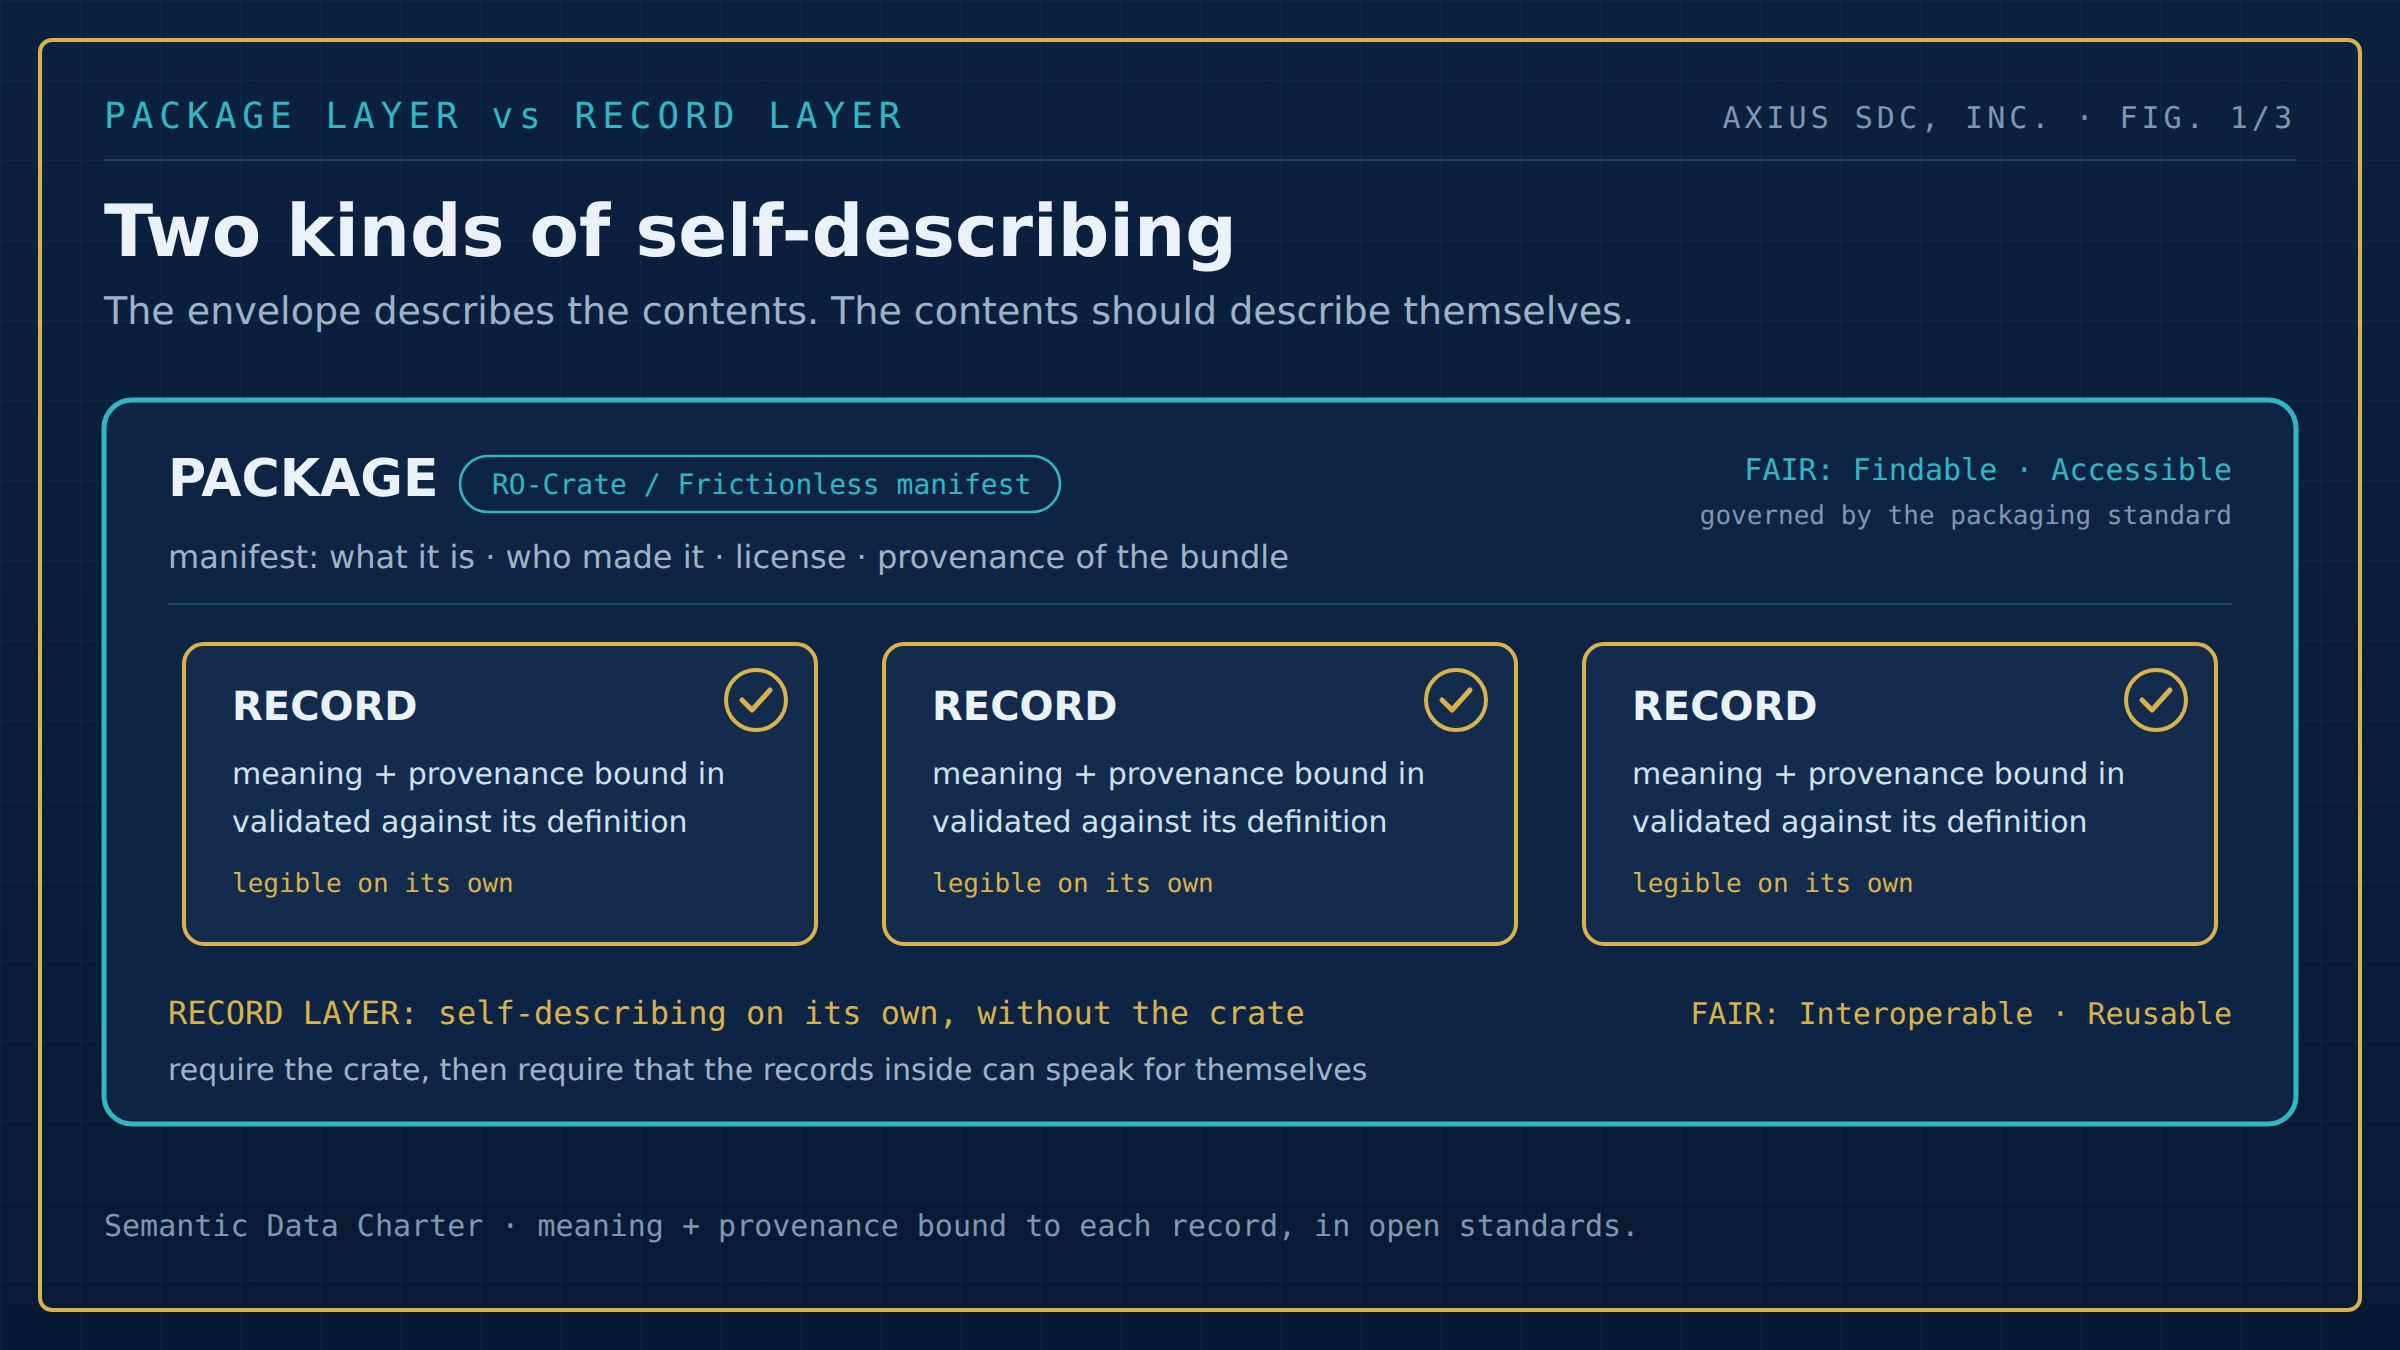
There is the package being self-describing: the crate carries a manifest about the files inside it. And there is, each record being self-describing: the data itself means something on its own, without the crate around it and without the system that produced it.
RO-Crate solves the first. By design, it does not solve the second. It describes the crate, and it can annotate what is inside. What it does not do is constrain or verify that each record means what the metadata claims, or make a single record legible once it is separated from its packaging. The envelope describes the contents. It does not make the contents describe themselves.
That distinction sounds academic until you run it forward a few years.
The years-later test
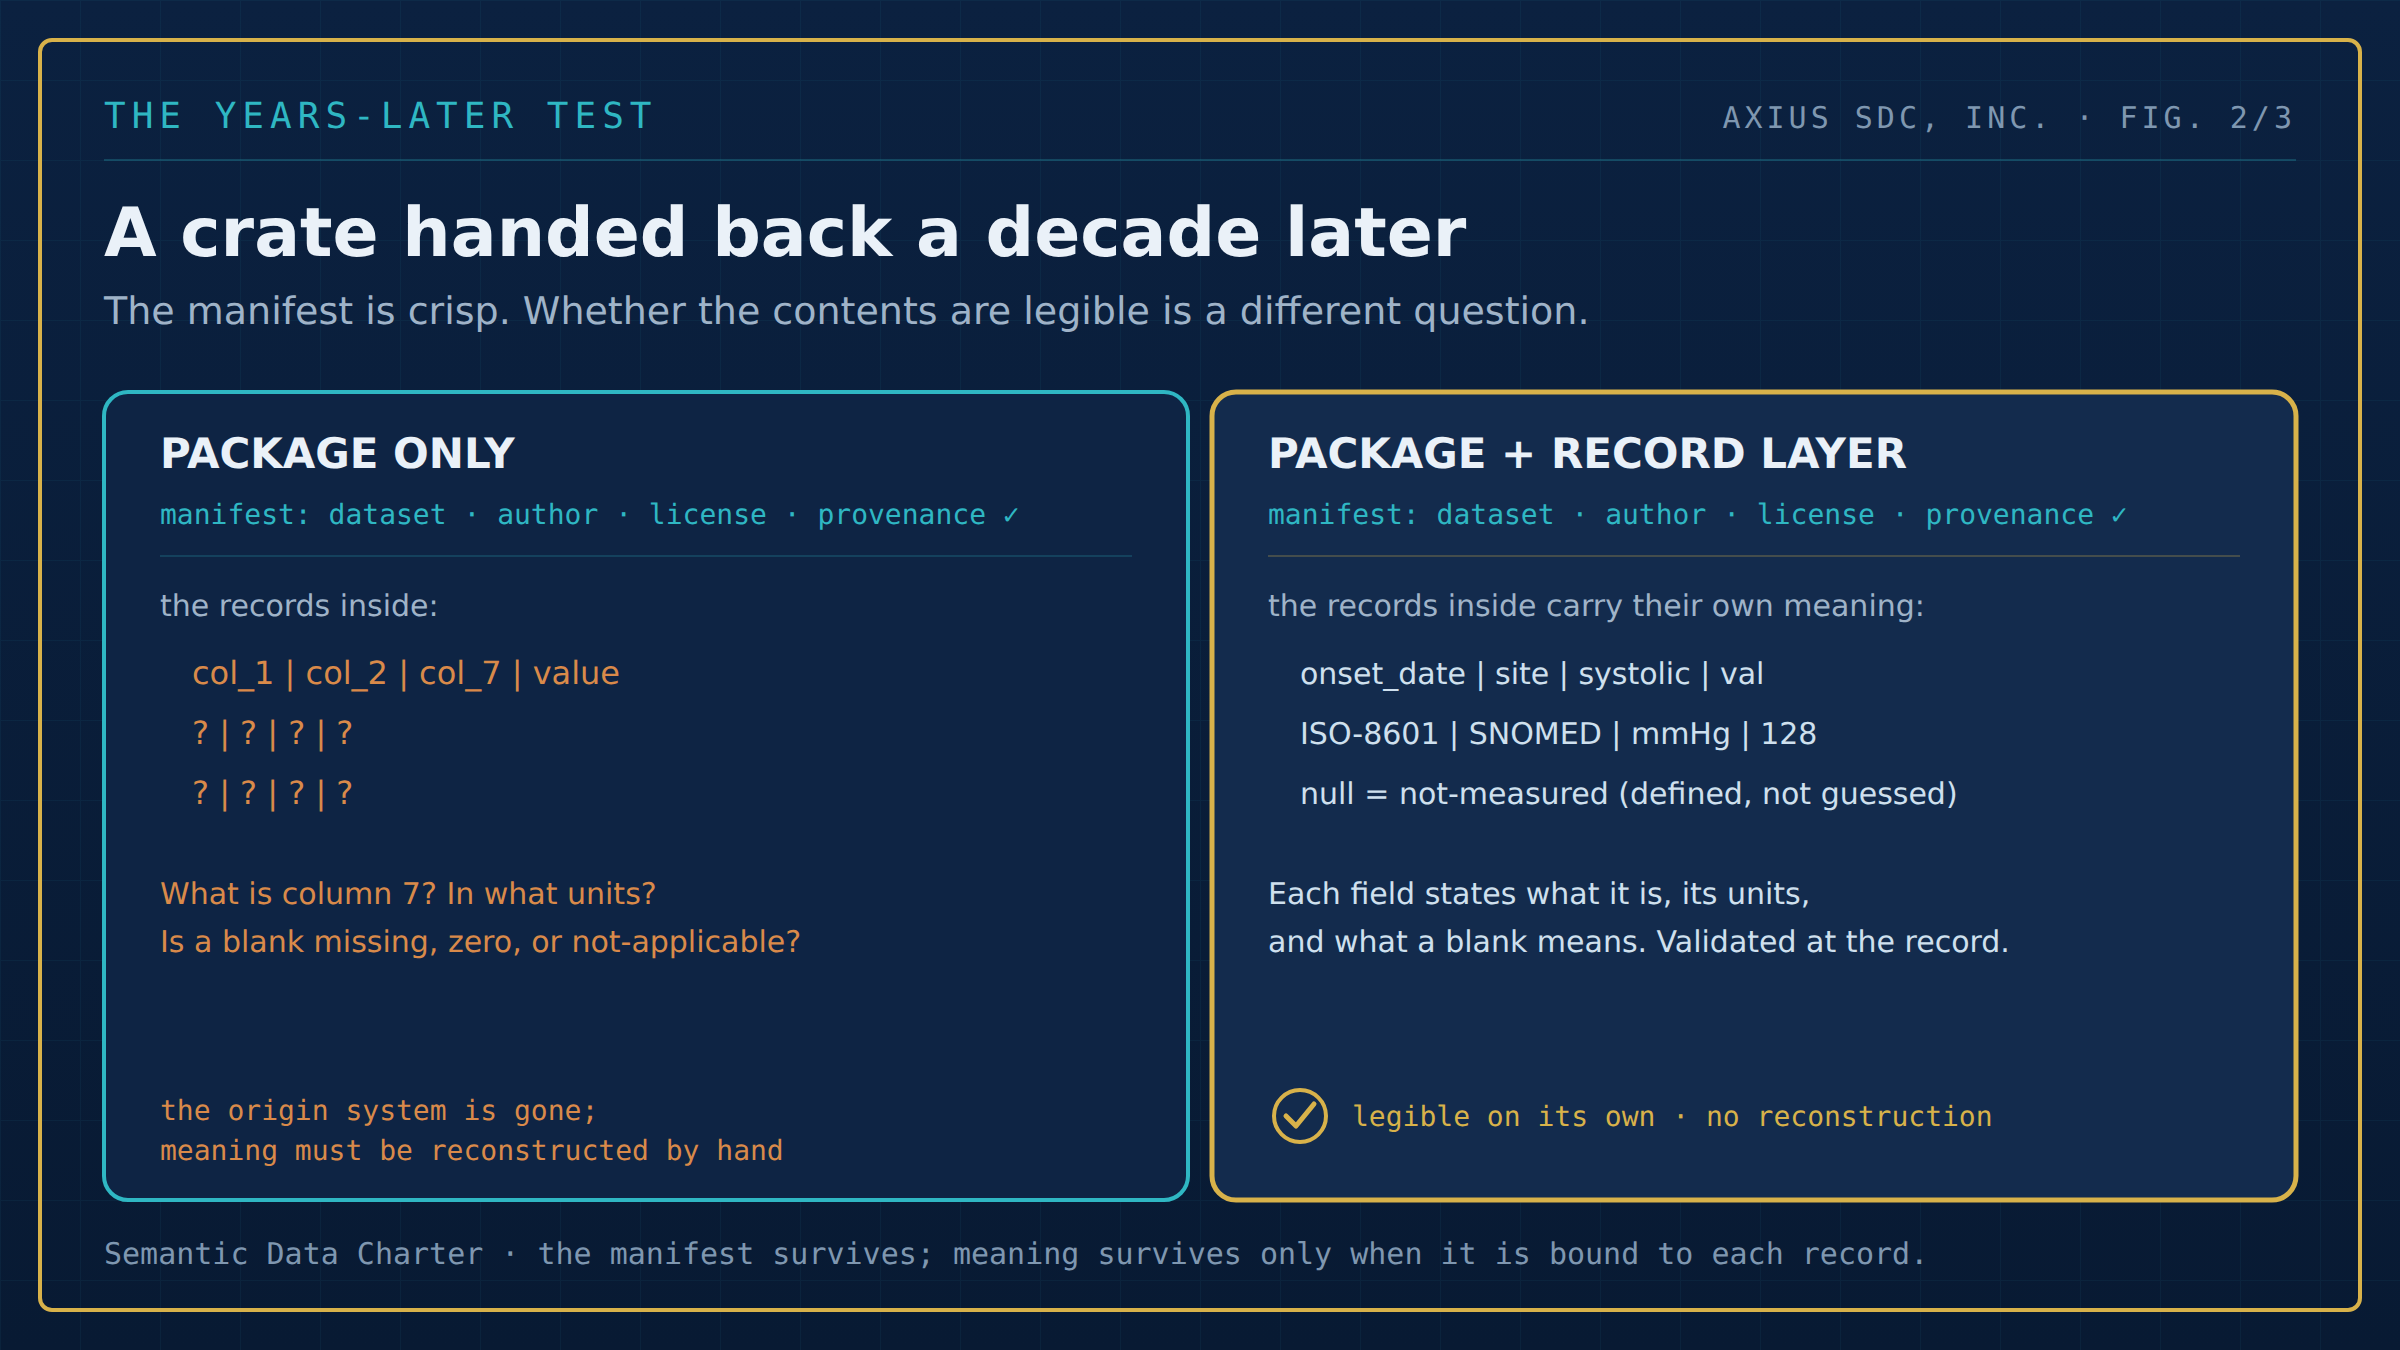
Picture the future the resilient-data community is actually building: dispersed, community-owned nodes designed to outlive the systems that filled them. A node hands you a crate a decade from now. The manifest tells you this is a materials science dataset, deposited by a lab that may no longer exist, under a license, and derived from an instrument run. Good. You open it, and inside is a table of numbers with column headers a human once understood. What does column seven mean? In what units? What was excluded? What does a blank in that field signify, missing, zero, or not-applicable? The crate cannot tell you, because that was never its job. You are back to reconstructing meaning downstream, which is the exact tax the packaging was supposed to end.
Now the interoperability version. Two well-packaged datasets from two projects touch the same domain. Both crates are impeccable. Nothing in either crate guarantees that “sample” in one means “sample” in the other, or that a measurement in one is comparable to a measurement in the other. The packages are findable and accessible. Whether they are interoperable is a property of the records, not the envelope, and the envelope was never asked to enforce it.
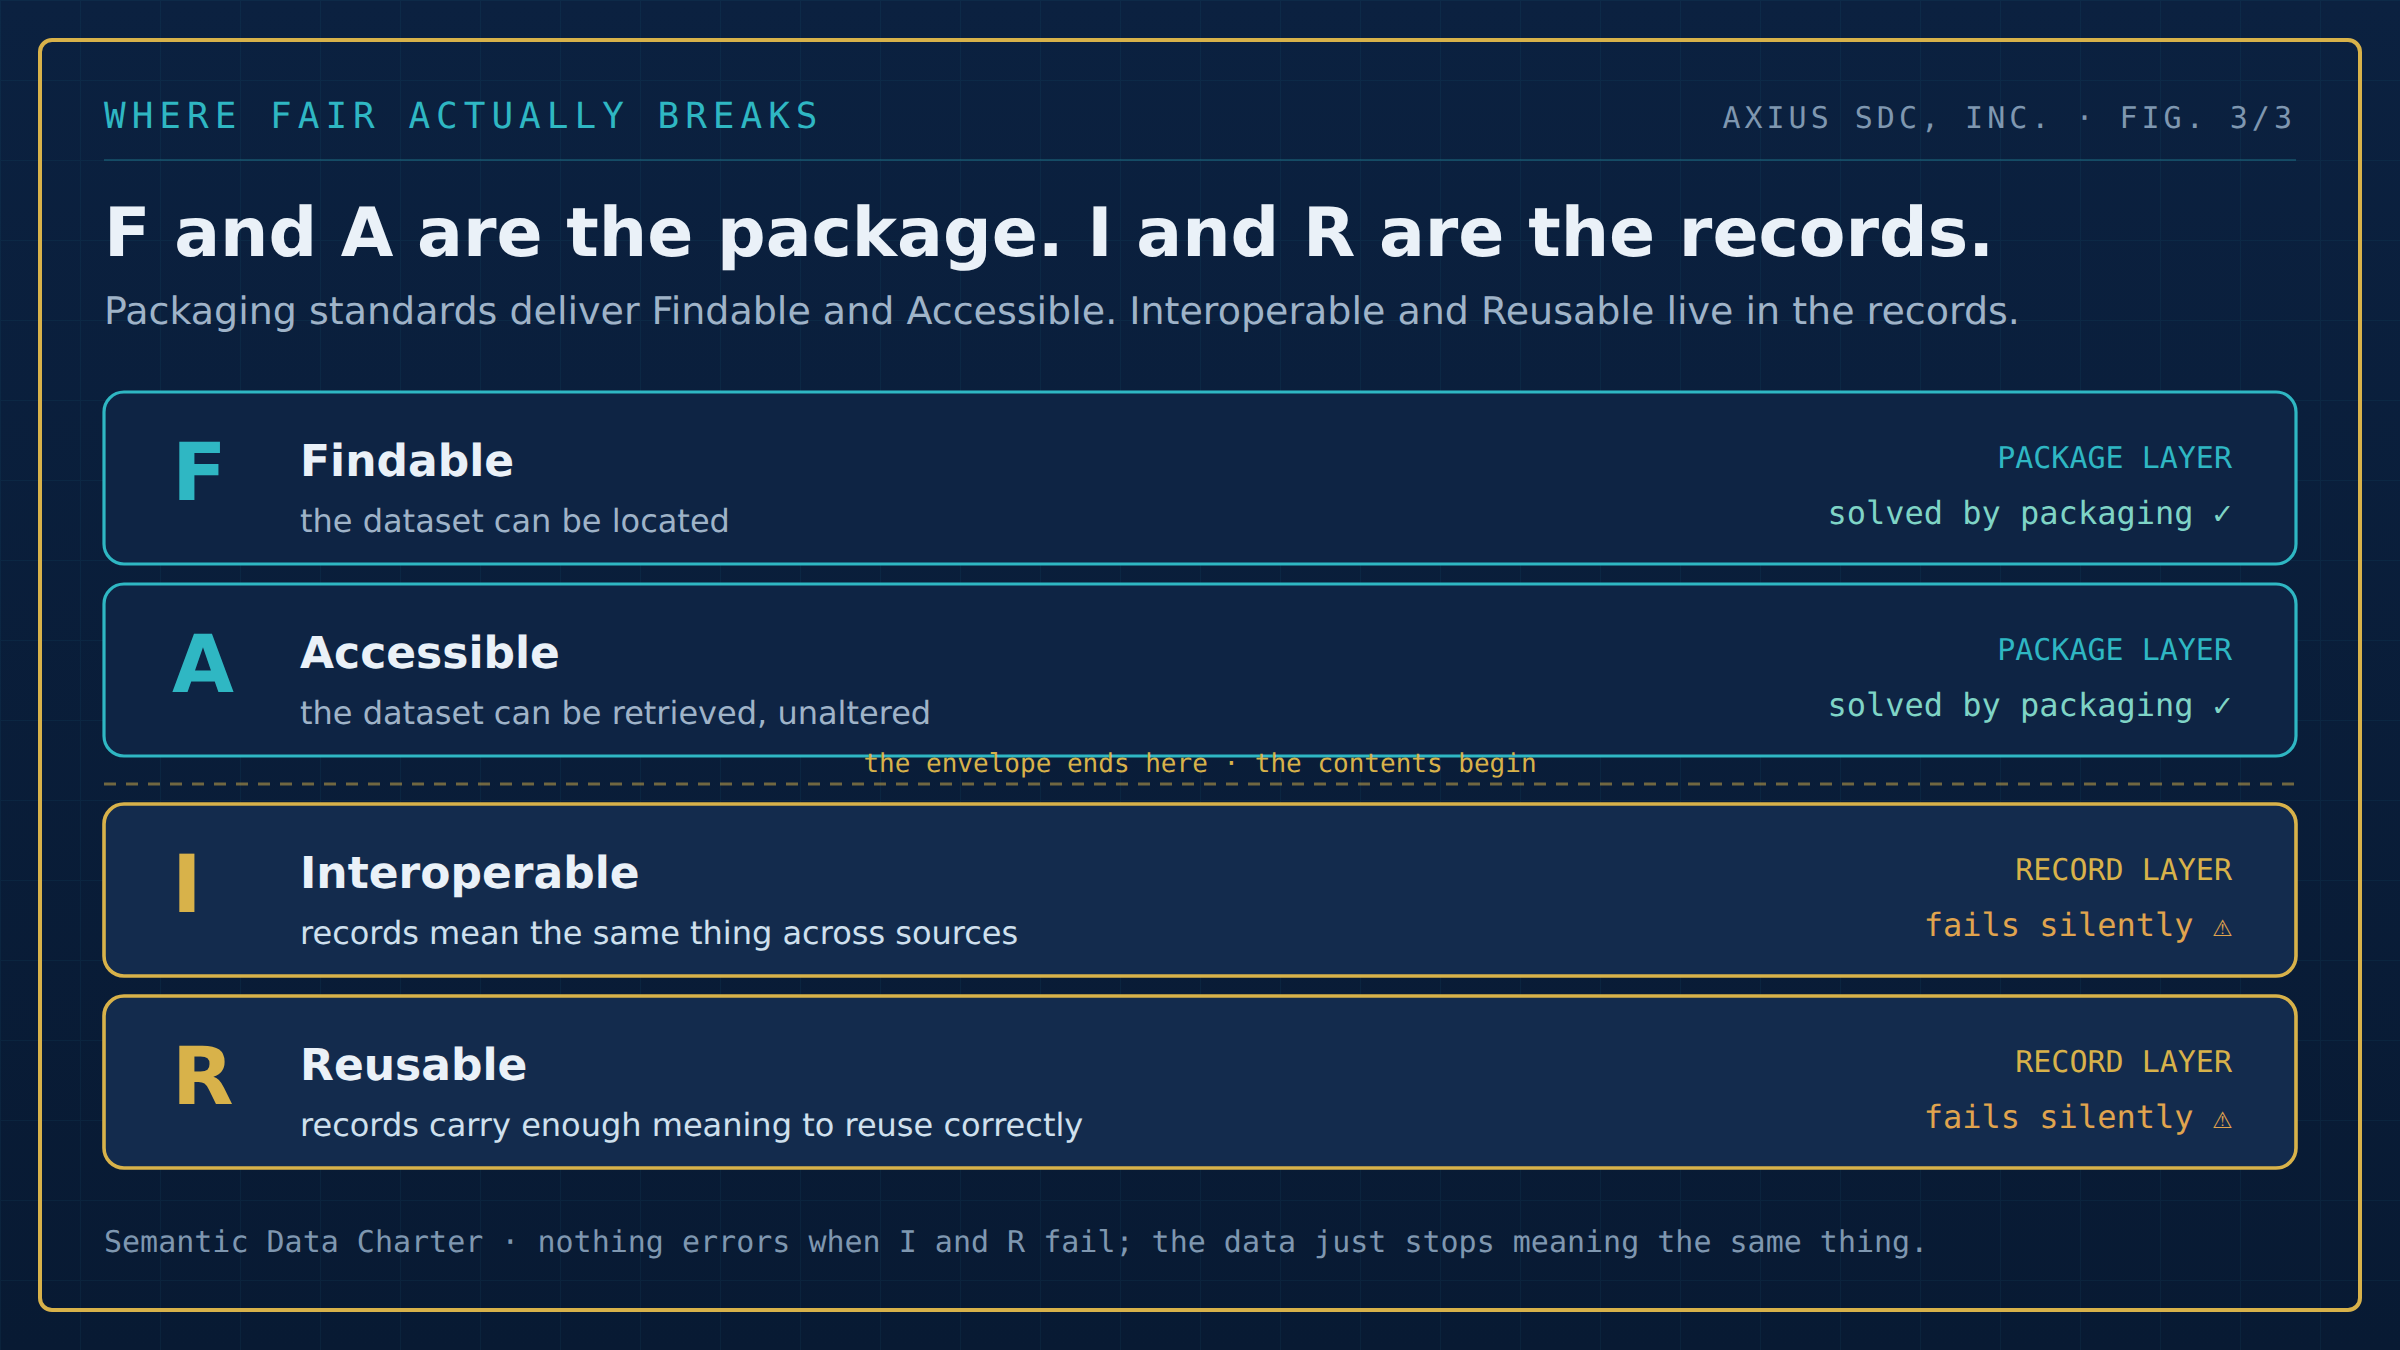
This is the quiet failure mode in FAIR. Findable and Accessible are largely package-level wins, and packaging standards deliver them well. Interoperable and Reusable are record-level properties that fail silently. No errors. The data simply does not mean the same thing when it lands somewhere else, and no one notices until an analysis produces a wrong number that looks perfectly reasonable.
The record layer
So what does self-describing at the record level actually require? The meaning and the provenance have to be bound into each record through a shared reference model, so that the record validates against its own definition, carries what it means, and stays legible with neither the packaging nor the origin system in the room. A record you can hand to a stranger, or to a machine, that can say what it is and prove it conformed.
This is the layer we work on. The SDC4 Reference Model is openly documented and standards-based: it uses W3C XML Schema 1.1 as the definition language, and RDF, SHACL, PROV, and JSON-LD as the outputs. A record generated against it is validated, its provenance is bound in, and it serializes to formats a repository already speaks. It is not a rival to the packaging standards. It is what belongs inside them.
Require the crate. Then make the contents legible.
The answer is not RO-Crate or a record layer. It is an RO-Crate with self-describing records inside. The crate stays the on-ramp: it makes the dataset findable, attributed, licensed. The records carry their own meaning and their own proof, so they survive the trip to the next node, the next project, the next decade. The envelope describes the contents; the contents describe themselves. A validated SDC instance drops cleanly inside an RO-Crate, so this is additive to everything the FAIR community has already built, not a replacement for any of it.
This is being decided right now. Consortia and resilient-data networks are writing their requirements this year, and the default is to require the package and stop there. That locks in the silent interoperability failure at the exact moment these systems are meant to last for decades. It is cheap to fix at design time and expensive to discover in year eight.
If you are writing those requirements, the sharpest single sentence is this: require a packaging standard for the box, and require that the records inside are self-describing and validatable on their own. The first keeps your data findable. The second keeps it meaningful, which is the part that compounds every time the data is reused.
The label is necessary. It is not sufficient.
A well-labeled box of mystery files is still a box of mystery files. The label was the hard-won, correct first step, and the community should keep requiring it. But the difference between a dataset you can find and a dataset you can trust is whether the contents can speak for themselves, without the box, without the manifest, and without the people who are no longer in the room.
Axius SDC, Inc. binds meaning and provenance into each data record with the openly documented SDC4 Reference Model, and generates validated RDF, JSON-LD, SHACL, and PROV from one bound instance. Standards-based, Apache-2.0, available now. More at semanticdatacharter.com.